What was tested?
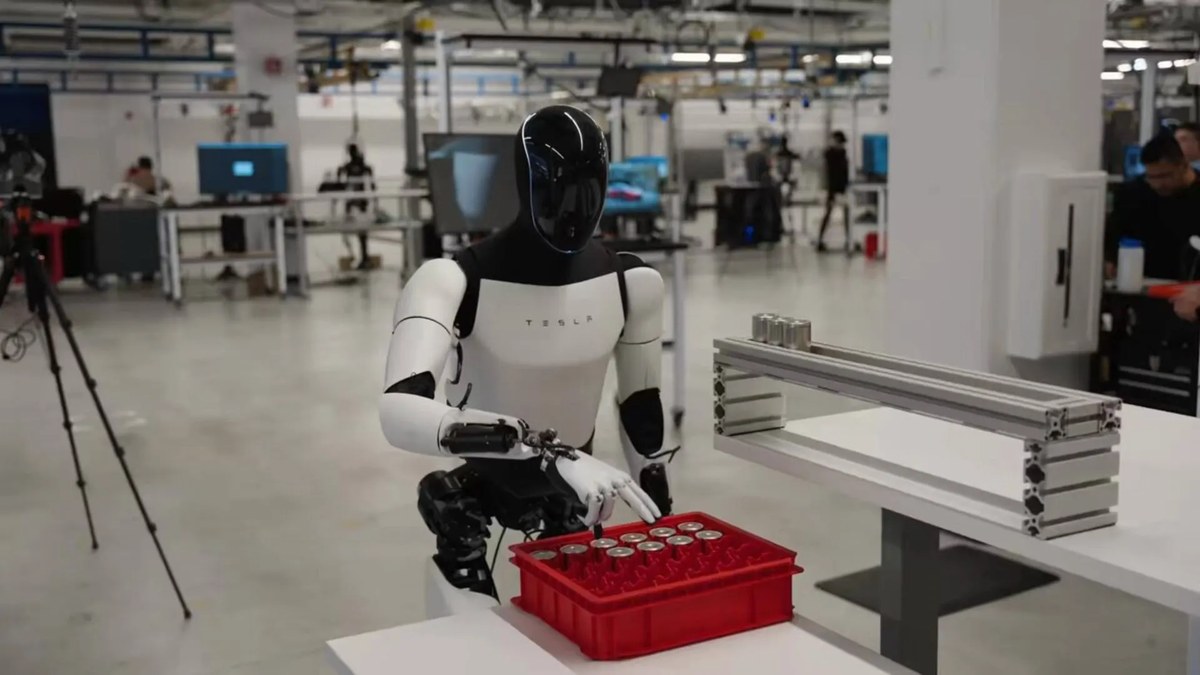
RoboColosseum evaluated five vision-language-action (VLA) policies, the AI systems that turn camera input and instructions into robot movements, plus three frontier AI agents. It ran 5,699 real-robot comparisons across 124 sites.
ADVERTISEMENT
Get the daily AI briefingSubscribe
What were the results?
Rankings varied across different robots and test tracks, meaning a policy that did well on one robot did not necessarily lead on another. On the G1 humanoid robot, no policy completed any task.
Why does it matter?
Most robot AI results come from a single lab or simulation. Testing on real hardware in many places gives a more honest picture of reliability, and it suggests humanoid robots remain far from general-purpose use.
✓ WE KNOW
- The benchmark covered 124 sites and 5,699 comparisons.
? STILL UNCLEAR
- How quickly policies will improve on humanoids.
> frequently_asked_questions
What is a VLA policy?
A vision-language-action model takes images and instructions and outputs robot actions.
> how_we_reported_this
- ✓Sources: written from primary sources and official statements, linked above.
- ✓Fact-check: names, dates and claims checked against the original sources.
- ✓AI use: researched with AI tools; written and reviewed by our editors. Our AI policy
- ✓Independence: UpdateNext has no financial relationship with the companies covered.
4 views
> react:
Comments